A geo lift test is a quasi-experimental or randomized geographic holdout that measures incremental outcomes by comparing treated regions against synthetic or matched controls, typically using Synthetic Control Methods (SCM). The industry also calls this a geo holdout test or matched market test, and the terms are interchangeable in practice.
The operational verdict: Run a geo lift test when you can isolate spend by geography, have enough regional conversion volume to detect your minimum meaningful lift, and need a causal, cookie-independent read on incrementality that platform-reported ROAS cannot give you.
Here is what you can expect from a well-designed test:
- Causal evidence. Not correlation, not modeled attribution. A real counterfactual.
- Cookie independence. No reliance on pixel tracking, last-click windows, or platform attribution models.
- Business-language outputs. Incremental revenue, incremental ROAS, and a confidence interval your CFO can act on.
- MMM calibration fuel. Geo-lift testing is widely used by large advertisers to cross-validate Marketing Mix Models and de-risk budget decisions.
Typical test lengths run 2–6 weeks for consumer campaigns and 8–16 weeks for higher-consideration or B2B purchases, but the correct test duration is conditional on conversion volume — in low-volume or B2B contexts, longer windows are required to reach sufficient power. See the Key Takeaways table for details.
Pro Tip: Before you design a single holdout region, run a power calculation. Most inconclusive geo tests are not a measurement problem. They are a design failure, and the GeoLift power calculator catches that failure before you spend a dollar.
Key Takeaways
A well-powered geo lift test with a pre-period RMSPE below 5% and a placebo rank in the top 10% produces the most defensible causal incrementality evidence available to a marketing team operating without cookie-based attribution.
| Point | Details |
|---|---|
| Power analysis is the design gate | Run NumberOfTestSitesGivenPower before committing; an underpowered test produces false negatives, not useful data. |
| Pre-period RMSPE is your reliability signal | A pre-period RMSPE above 5% means redesign the donor pool, not interpret the result. |
| iROAS drives the budget decision | Incremental ROAS = incremental revenue divided by incremental spend; compare against contribution margin breakeven to scale or cut. |
| Test length scales with conversion volume | Low-volume or B2B contexts need 8–16 weeks and pipeline metrics rather than closed revenue to reach 80% power. |
| Ashafrazier builds the full system | From power analysis and SCM execution to MMM integration and executive reporting, the geo test feeds a compounding growth decision loop. |
Table of Contents
- What is a geo lift test and when should you use one?
- How GeoLift and Synthetic Control Methods build the counterfactual
- How to select markets and set up the pre-test correctly
- How to run a power analysis before you commit to a design
- Running the test: what to do from launch to close
- Analyzing results: from raw lift to a decision your CFO will act on
- Common design failures and how to fix them
- Which tools should you use to run a geo lift test?
- A practitioner checklist for running geo lift tests inside a growth system
- When geo experiments are worth the effort and when they are not
- Geo lift test design is a service, not just a skill
- Sources
What is a geo lift test and when should you use one?
A geo lift test, geo holdout test, and matched market test all describe the same core design: divide geographies into treatment and control groups, run your campaign only in treatment regions, and measure the difference in outcomes. The formal industry term is geo experiment, as established in Google's foundational research on measuring ad effectiveness with region-level randomization.
How it compares to other incrementality methods
The choice of method depends on your data structure, channel, and the precision you need.
- Platform lift studies (Meta, Google) use user-level holdouts within the platform's own ecosystem. They are fast and cheap, but they measure incrementality only within that platform's attributed users, not total business impact.
- User-level RCTs require cookie or login-based assignment. They are precise but increasingly unreliable as third-party tracking degrades.
- Marketing Mix Models (MMM) give a continuous, portfolio-level view but are modeled, not experimental. They need periodic calibration against causal evidence.
- Ghost bids (PSA holdouts) work inside a single DSP. They cannot measure cross-channel or offline lift.
Geo lift tests sit at the intersection of causal rigor and operational feasibility. They are the right choice when:
- Your campaign runs across channels that cannot share a common user identifier.
- You need to measure offline or in-store impact alongside digital.
- You are validating or calibrating an MMM coefficient.
- Platform-reported ROAS looks implausibly high and you need an independent check.
Limitations to know before you commit
- Spillover. Consumers cross geographic boundaries. A holdout in Chicago's North Side leaks if your ads reach South Side residents who shop in both areas.
- One change at a time. A geo test measures one treatment. Running a concurrent promotion in test regions contaminates the result.
- Infrequency. You cannot run geo tests continuously without exhausting your donor pool or fatiguing your holdout regions.
- Minimum volume floor. Low-conversion geographies cannot produce statistically reliable results without very long test windows.
How GeoLift and Synthetic Control Methods build the counterfactual
The core question a geo lift test answers is: what would have happened in the treatment regions if the campaign had never run? That counterfactual is what SCM constructs.
How the synthetic control is built
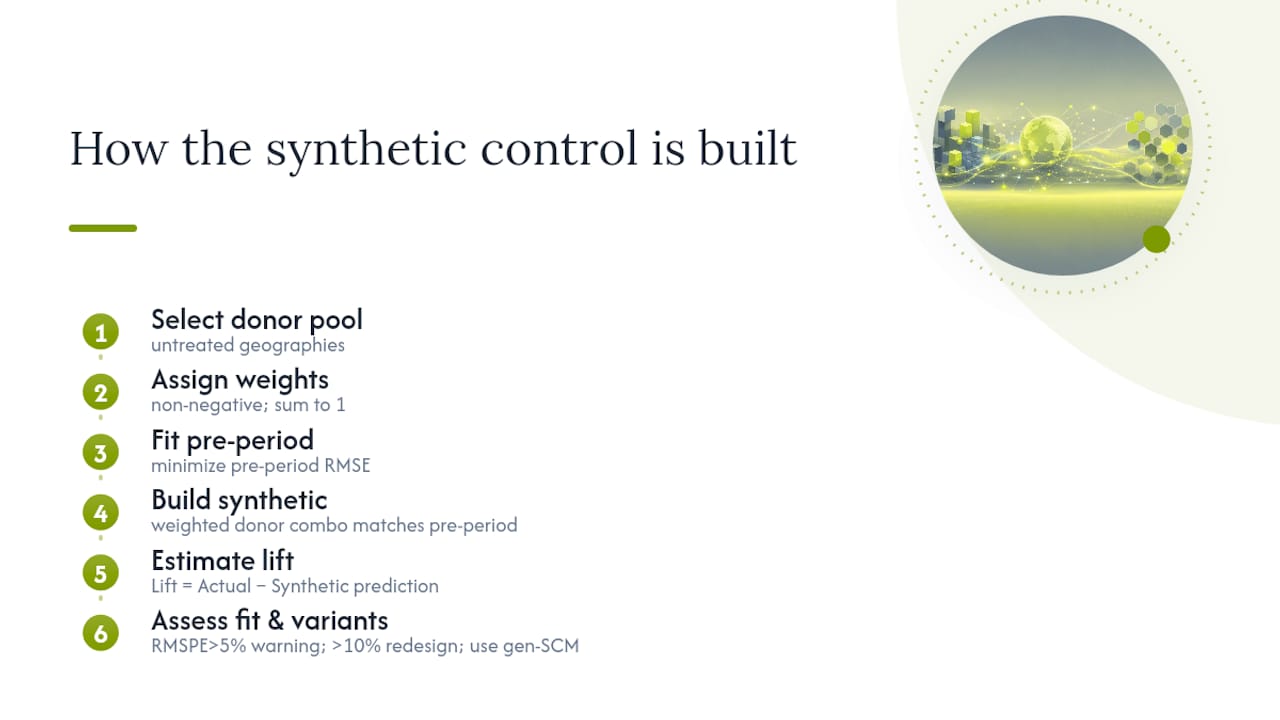
SCM takes a donor pool of untreated geographies and assigns them weights so that the weighted combination, the synthetic control, matches the treatment region's pre-period outcome as closely as possible. The weights must sum to 1 and are constrained to be non-negative, which prevents extrapolation outside the observed data range. The objective function minimizes pre-period RMSE (root mean squared error) between the treatment and its synthetic twin.
Once the test period begins, the synthetic control continues on its pre-period trajectory. The gap between actual treatment outcomes and the synthetic control's predicted path is the estimated incremental lift.
The core lift calculation: Incremental lift = Actual treatment outcome minus Synthetic control prediction. The reliability of that estimate depends entirely on how well the synthetic control tracked the treatment region before the campaign launched. A pre-period RMSPE above 5% is a warning sign; above 10% is a redesign trigger.
The Berkeley working paper on SCM demonstrates that synthetic-difference-in-differences and generalized SCM approaches reduce bias from interactive fixed effects and time-varying confounders compared with simple matched-pair comparisons. When your donor pool contains regions with diverging trends, a generalized synthetic control that accounts for interactive fixed effects is more reliable than standard SCM.
Why SCM beats single-pair comparisons
A single matched-pair design (one treatment city, one control city) is fragile. If the control city experiences an idiosyncratic shock, your entire result is contaminated. SCM spreads that risk across a weighted donor pool. A shock to one donor region shifts the synthetic control only proportionally to that region's weight, not catastrophically.
The causal inference framework underlying geo experiments, rooted in the Rubin causal model, requires that the treatment assignment be independent of potential outcomes. Geographic randomization, when properly designed, satisfies that requirement.
Robustness checks SCM enables
- Placebo tests. Assign the treatment label to donor regions and re-run the SCM. If the estimated lift in placebo markets is as large as the real result, your finding is not credible.
- Permutation tests. Shuffle treatment assignment across all geographies and build a distribution of null effects. Your observed lift should sit in the tail of that distribution.
- Rolling-window pre-period fits. Shorten or extend the pre-period and check whether the synthetic control remains stable.
- Pre-period falsification. Artificially end the pre-period early and treat the remaining pre-period as a fake test. Lift should be near zero.
How to select markets and set up the pre-test correctly
Poor market selection is the most common structural failure in geo experiments. The Metricuno incrementality guide makes this point directly: avoid gut-feel matching. Use statistical matching and run equal-length pre-test windows to validate parallel trends.
Data requirements
You need at least 8–12 weeks of pre-period data at weekly granularity before you can reliably build a synthetic control. The KPI should be a clean, geography-tagged business metric: weekly net revenue, weekly orders, or weekly conversions. Avoid using platform-reported conversions as your primary KPI; they carry attribution bias. Use your own transaction data.
| Data element | Why it matters | Example |
|---|---|---|
| Weekly outcome metric | Builds the pre-period fit baseline | Net revenue by DMA or ZIP cluster |
| Geographic tag | Assigns each transaction to a region | Shipping ZIP, store location, IP-based DMA |
| Campaign spend by region | Confirms treatment isolation | Ad platform geo-targeting logs |
| External event calendar | Flags confounders during pre-period | Holidays, competitor promotions, weather events |
| Demographic proxies | Improves donor pool matching | Population, median income, category penetration |
Market selection strategies
A single large metro as your treatment region is the simplest design, but it concentrates risk. A clustered approach using 5–10 treatment regions spread across different DMAs reduces idiosyncratic risk and gives SCM more variance to work with. Your donor pool should be at least three times the size of your treatment group, ideally 20–40 regions.
Matching criteria, in priority order: historical trend similarity over the pre-period, sales seasonality alignment, demographic similarity, and geographic non-contiguity with treatment regions.
Isolation tactics
Spillover is the silent killer of geo tests. Buffer regions, geographies adjacent to treatment markets that receive neither treatment nor control designation, absorb cross-border ad exposure. For digital campaigns, confirm that your ad platform's geo-targeting is set to people in this location, not people interested in this location. The latter targets users who have shown interest in a region but may live elsewhere, contaminating your holdout.
Pro Tip: Before launch, run a pre-period RMSPE check. If the synthetic control's pre-period fit exceeds 5% RMSPE, redesign the donor pool or extend the pre-period before you spend a dollar on the test.
How to run a power analysis before you commit to a design
Power analysis is not optional. It is the gate that separates a credible test from an expensive guess. GeoLift's methodology documentation provides two key routines: NumberOfTestSitesGivenPower, which estimates how many treatment markets you need to detect a target lift at a given power level, and EffectGivenSitesAndTime, which estimates the minimum detectable effect (MDE) given a fixed number of markets and test weeks.
The three drivers of power
- Effect size. The larger the true lift, the easier it is to detect. A 5% lift requires far more power than a 20% lift.
- Outcome variance. High week-to-week volatility in your KPI demands more markets or longer duration to separate signal from noise.
- Sample size. In geo tests, sample size is the product of treatment markets multiplied by test weeks.
Practical scenarios
| Baseline weekly orders | Expected lift | Suggested treatment geos | Recommended weeks |
|---|---|---|---|
| — | 15% | 3–5 DMAs | 4–6 |
| — | 8% | 6–8 DMAs | 6–8 |
| — | 10% | 8–12 DMAs | 8–12 |
| 50 | 15% | 12–15 DMAs | 12–16 |
For B2B contexts, Prooflytics' geo holdout guide notes that reaching 80% power typically requires 10–15 matched pairs and longer durations, with pipeline metrics standing in for closed revenue when conversion volume is too low.
When volume is genuinely too low for a clean geo test, three options exist: extend duration rather than shrink the geographic sample, use a leading indicator (add-to-cart, qualified leads) instead of closed revenue, or accept a platform-level lift study as a lower-confidence proxy.
Pro Tip: Run NumberOfTestSitesGivenPower with your actual historical data before finalizing the test design. The output will tell you whether your planned design has 80% power or 40% power, and those two numbers lead to completely different decisions.
Running the test: what to do from launch to close
A geo lift test that is designed well can still be ruined by poor execution. The operational discipline during the test window matters as much as the pre-test setup.
Launch checklist
- Confirm holdout regions have zero ad spend across all relevant channels, not just the primary platform.
- Freeze creative, pricing, and promotional offers in treatment regions for the test duration.
- Notify sales, customer success, and local field teams that a measurement window is active. Undisclosed promotions or sales outreach in holdout regions are contamination events.
- Set up a daily data pipeline that tags transactions by geography and feeds a monitoring dashboard.
- Document the pre-registered analysis plan: which KPI, which SCM specification, which pre-period window, and which significance threshold.
What to monitor during the test
- Weekly RMSPE. If the synthetic control begins diverging from its pre-period fit pattern before the test ends, investigate immediately.
- Ad spend by region. Confirm treatment regions are receiving spend and holdout regions are not. Platform delivery reports lie more often than you expect.
- External event flags. A major weather event, a competitor store opening, or a regional supply disruption in a treatment or control market should be logged with dates.
Mid-test intervention rules
Some events are fatal to the test and require a restart: a price change in treatment regions, a promotional discount not applied to holdout regions, or a major product launch. Others can be logged and adjusted for in post-analysis: a minor supply disruption affecting one treatment market, a national holiday that affects all regions equally.
The rule is simple. If the event creates a differential between treatment and control that is unrelated to your campaign, the test is contaminated. Log it, stop the test, and redesign.
Analyzing results: from raw lift to a decision your CFO will act on
Post-test analysis has two jobs: produce a credible lift estimate with honest uncertainty bounds, and translate that estimate into a business decision.
Outputs to produce
- Absolute lift. Total incremental units or revenue in treatment regions during the test period.
- Percent lift. Absolute lift divided by the synthetic control's predicted baseline.
- Incremental revenue ($). The dollar value of the absolute lift, extrapolated to the full campaign footprint.
- Incremental ROAS. Incremental revenue divided by incremental spend. This is the number that drives budget decisions.
- Confidence interval. The range within which the true lift falls at your chosen significance level (typically 90%).
- Pre-period RMSPE. Reported alongside results as a reliability indicator.
Incremental ROAS formula: iROAS = Incremental Revenue / Incremental Spend. Example: $400,000 in incremental revenue against $80,000 in incremental spend yields an iROAS of 5x. Compare that against your contribution margin breakeven to decide whether to scale. Practitioner analyses have found that branded paid-search geo holdouts frequently produce iROAS materially below platform-reported ROAS, sometimes under 1x, which is exactly why you run the test.
Robustness checks before you present
Run placebo tests by assigning the treatment label to each donor region in turn and re-estimating lift. If your observed lift ranks in the top 10% of the placebo distribution, you have a credible result. If it does not, you have a directional signal at best. Also test sensitivity to donor-pool exclusion: drop your highest-weighted donor region and re-run. A result that collapses when one region is removed is fragile.
Pro Tip: In small-sample geo tests with fewer than 10 treatment markets, a p-value below 0.10 is a directional result, not a certification. Present the confidence interval and the placebo rank alongside the p-value. Executives who see only a p-value will either over-trust or dismiss the result.
What to show executives
- One-line verdict: "The campaign drove X% incremental lift in treatment regions, with a 90% confidence interval of Y% to Z%."
- Business impact: incremental revenue and iROAS.
- Reliability signal: pre-period RMSPE and placebo rank.
- Recommended action: scale, hold, or retest with more power.
For guidance on building the KPI dashboard that surfaces these outputs in a format stakeholders can act on, the structure matters as much as the numbers.
Common design failures and how to fix them
Most inconclusive geo tests share the same root causes. Recognizing them before launch is far cheaper than diagnosing them after.
The failure modes
- Underpowered design. The most common failure. The test was designed without a power calculation, and the true lift was smaller than the MDE. Result: a false negative that gets interpreted as "the campaign doesn't work."
- Non-parallel pre-trends. Treatment and donor regions were trending differently before the test started. The synthetic control cannot fit the pre-period, and any post-period gap is uninterpretable.
- Spillover contamination. Holdout consumers were exposed to ads through cross-border targeting, shared media markets, or word-of-mouth. The holdout is not clean.
- Concurrent campaigns. A separate promotion, a sales push, or a PR event ran in treatment regions during the test window. The lift estimate is a blend of multiple causes.
- Measurement gaps. Transaction data was not tagged by geography, or the data pipeline had latency that corrupted the weekly time series.
Practical fixes
- Extend test duration before shrinking the geographic sample. More weeks beats fewer markets for power.
- Reselect or cluster regions when pre-trends diverge. Add buffer geographies around treatment markets.
- Pre-register the analysis plan before the test launches. This prevents post-hoc specification searching that inflates apparent significance.
- Use leading indicators (add-to-cart, qualified leads, store visits) when closed-revenue volume is too low.
Pro Tip: When results are insignificant, run this diagnostic sequence: check power first (was the MDE achievable?), then check contamination (were holdout regions clean?), then run placebo tests (does the distribution support the observed lift?). If all three checks fail, the test needs a redesign, not a reinterpretation. Avoid the common strategic mistake of retrofitting a narrative onto a flawed measurement design.
Which tools should you use to run a geo lift test?
The tooling ecosystem for geo experiments is mature and largely open-source. Your choice depends on the complexity of your design and your team's technical stack.
GeoLift (Meta / Facebook Incubator)
GeoLift is an R package built specifically for geo lift experiments. It handles power analysis, synthetic control estimation, placebo testing, and result visualization in a single workflow. The NumberOfTestSitesGivenPower and EffectGivenSitesAndTime functions are the most practically useful power-analysis tools available in open-source geo experiment tooling. The GeoLift methodology documentation includes worked examples and reproducible code.
Use GeoLift when you want a full-featured, opinionated workflow that covers design through analysis.
Google CausalImpact
CausalImpact (R and Python) uses a Bayesian structural time-series model to estimate the counterfactual. It is simpler than GeoLift's SCM implementation and works well for single-treatment, single-region analyses. It does not include a built-in power calculator, so you need to run simulations separately.
Use CausalImpact when your design is a single treated region against a clean donor pool and you want a fast, interpretable output.
SCM libraries
For teams that want direct control over the SCM specification, the Synth package in R implements the Abadie et al. original SCM estimator. Python equivalents include pysyncon and SyntheticControlMethods. These give you more flexibility but require more manual setup.
Commercial platforms
When operational scale, automation, and cross-channel integration matter more than methodological flexibility, commercial measurement platforms handle the data plumbing and reporting layer. They are worth the cost when your team lacks the engineering bandwidth to maintain custom pipelines.
On reproducibility: Whatever tool you use, pre-register your analysis plan, version-control your code, and document the donor pool selection criteria before the test launches. A geo lift result that cannot be reproduced from the raw data is not a result you can defend to a CFO or a board.
Google's geo-experiments paper remains the clearest published framework for understanding why geographic randomization produces interpretable, defensible causal estimates. The Measured practitioner guide covers operational execution, including automation and region selection, for teams running tests at scale.
A practitioner checklist for running geo lift tests inside a growth system
This is the operational sequence used to design, gate, and act on geo experiments as part of a compounding growth system, not as one-off measurement exercises.
Pre-test approvals and setup
- Define the business question: which channel, which audience, which KPI.
- Run a power calculation. If the MDE is above 20% and your expected lift is 8%, do not run the test. Redesign or use a different method.
- Model the expected revenue dip in holdout regions for the finance team. A holdout is a deliberate pause in spend; finance needs to know the short-term cost before approving the design.
- Assign a measurement owner who is not the channel manager. Separation of roles prevents motivated reasoning in the analysis.
- Set the analysis plan in writing: KPI, SCM specification, pre-period window, significance threshold, and decision rules for scale vs. hold.
Decision thresholds
- Scale: iROAS exceeds contribution margin breakeven AND the 90% confidence interval lower bound is positive AND placebo rank is in the top 10%.
- Hold and retest: iROAS is above breakeven but the confidence interval crosses zero. Increase test duration or geographic sample and rerun.
- Kill: iROAS is below breakeven at the lower bound of the confidence interval. Reallocate budget.
These thresholds are not arbitrary. They connect directly to unit economics: if the incremental revenue per dollar spent does not cover your contribution margin, scaling that channel destroys value regardless of what the platform dashboard says. The LTV:CAC framework provides the right lens for translating iROAS into long-term acquisition economics.
Integration with MMM and budget cadence
Run geo tests on a rotating quarterly schedule, not continuously. Each completed test produces a calibration data point for your MMM. Feed the geo-derived iROAS back into the MMM as a prior or validation coefficient for the tested channel. Over four to six quarters, this creates a compounding measurement loop: the MMM gets more accurate, the geo tests get better-targeted, and budget allocation decisions get progressively less speculative.
The operational principle: Geo lift tests are not a measurement tool. They are a budget decision tool. Every test should end with a specific reallocation recommendation, not just a lift estimate. If the team cannot connect the result to a dollar amount moving from one channel to another, the test was not designed with enough business context.
Operational vignette
Consider a mid-market DTC brand running connected TV and paid social across 40 DMAs. The platform dashboard shows a blended ROAS of 4.2x. A geo lift test may be designed with 8 treatment DMAs and 32 donor DMAs, a 10-week pre-period, and a 6-week test window. The power calculation confirms 80% power to detect a 12% lift. Post-test SCM analysis shows 9% incremental lift with a 90% CI of 4%–14% and a pre-period RMSPE of 2.8%. Placebo rank: top 8%. The iROAS on the tested channel comes out at 2.9x, well below the platform-reported 4.2x. Decision: reduce spend on that channel by 30%, reallocate to the channel that has not yet been tested, and schedule the next geo experiment for Q3.
That is what a geo lift test is actually for.
When geo experiments are worth the effort and when they are not
Geo experiments produce the highest return on measurement investment when the decision at stake is large, the channel is hard to attribute through other means, and the team has the operational discipline to execute a clean holdout. For a $50,000 monthly channel spend, a geo test that takes 6 weeks and costs 10% of that spend in foregone holdout revenue is a reasonable price for a causal answer. For a $5,000 monthly spend, the math rarely works.
Three quick rules for growth executives deciding whether to run a geo test:
- Frequency: Run one to two geo tests per quarter per major channel. More than that and you exhaust your donor pool and create holdout fatigue in your measurement regions.
- Channel selection: Prioritize channels where platform-reported ROAS is highest and most suspect. Those are the channels where the gap between reported and incremental performance is most likely to be large.
- MMM integration: Never run a geo test in isolation. Feed every result back into your MMM within 30 days of test close. A geo test that does not update a model or a budget is a measurement exercise, not a growth decision.
The city-level campaign consolidation lesson applies directly here: more geographic granularity is not always better. A well-designed test across 8 DMAs beats a poorly designed test across 40 ZIP codes every time.
Geo lift test design is a service, not just a skill
Most growth teams have the intent to run geo experiments. Few have the system to run them well, connect the results to budget decisions, and repeat the cycle quarterly without the process degrading into ad hoc measurement.
Ashafrazier builds the full measurement infrastructure: power analysis and market selection, SCM-based post-test analysis, MMM integration, and the executive reporting layer that turns a lift estimate into a reallocation decision. The work is grounded in the same unit economics discipline that has driven hundreds of millions in revenue across high-consideration markets, with an average ROAS of 7x across engagements. If you are sitting on a channel budget that platform dashboards say is working but you have never independently verified, that is the right starting point.
Use the Growth Score Calculator to model your unit economics and identify which channels are most worth testing. Or review the case studies to see how integrated measurement systems translate into compounding revenue growth. When you are ready to design your first geo experiment or overhaul an existing measurement program, book a diagnostic to get a clear-eyed assessment of where your attribution gaps are and what a geo test program would cost to run versus what it would likely return.
Sources
These are the primary references for the methodology, tooling, and practitioner guidance covered in this article.
- GeoLift Methodology
- Measuring Ad Effectiveness Using Geo Experiments
- How to Run Geo Testing for Marketers: A Step-by-Step Guide | Measured®
- Geo-Lift Testing 2026: A Practical Incrementality Framework · d-dat
- Geo Holdout Testing: A B2B Incrementality Guide | Prooflytics
- American Economic Association - JEP overview article
- Incrementality Testing: Geo Holdouts & Lift Studies Guide